
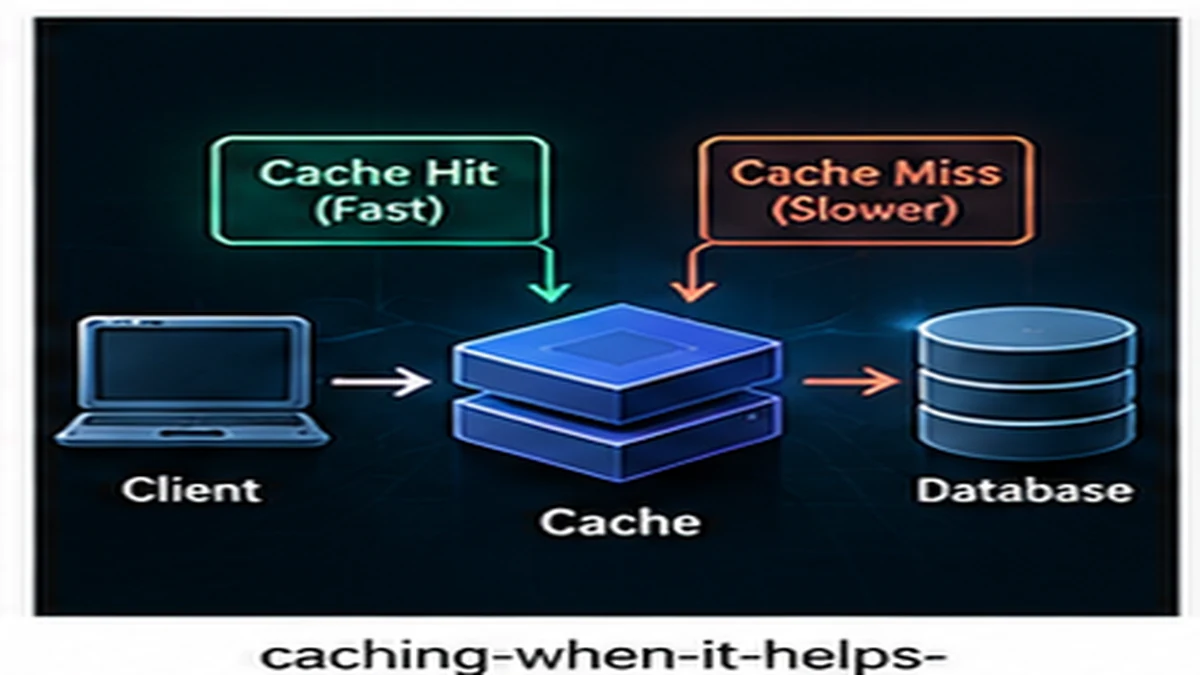
Caching stores frequently accessed data in memory to avoid repeated expensive operations. It reduces latency, decreases database load, and improves user experience when used correctly. It also introduces complexity: stale data, cache invalidation bugs, memory pressure, and debugging difficulties. Caching is powerful but not a universal solution.
What caching solves
Caching addresses specific performance problems.
Repeated expensive reads
If the same data is queried frequently and changes rarely, caching avoids redundant database queries. Examples: user profiles, product catalogs, configuration settings.
Slow computations
If calculating a result is expensive, caching the result avoids recalculation. Examples: report generation, aggregations, complex analytics.
External API calls
Third-party APIs have rate limits and latency. Caching responses reduces external dependencies. Examples: geocoding results, pricing data, weather information.
Database pressure
High-traffic applications can overwhelm databases with read queries. Caching reduces database load.
When caching helps
Caching delivers value under specific conditions.
High read-to-write ratio
Data read frequently but updated rarely benefits from caching. If data changes often, cache invalidation complexity increases.
Expensive operations
If fetching or computing data takes seconds, caching provides meaningful speedup. If operations are already fast (milliseconds), caching adds complexity for minimal gain.
Many identical requests
If users request the same data repeatedly, caching avoids duplicate work. If every request is unique, caching provides no benefit.
Acceptable staleness
If slightly outdated data is acceptable, caching works well. If real-time accuracy is required, caching introduces correctness problems.
Cache invalidation strategies
Cache invalidation is notoriously difficult. Stale cached data causes bugs.
Time-based expiration (TTL)
Cache entries expire after a fixed duration. Simple but data may be stale for the entire TTL period.
cache.set("user:123", userData, ttl=300) # 5 minutesManual invalidation
Application code invalidates cache when data changes. Requires discipline and can miss edge cases.
updateUser(userId, newData)
cache.delete("user:" + userId)
Write-through caching
Writes update both cache and database simultaneously. Keeps cache consistent but does not speed up writes.
Cache-aside pattern
Application checks cache first, fetches from database on miss, then populates cache. Common pattern but requires careful invalidation.
Problems caching creates
Stale data
Cached data becomes outdated when underlying data changes. Users see old information, leading to incorrect decisions or confusing experiences.
Cache invalidation bugs
Missing a cache invalidation in one code path causes hard-to-debug issues. Cache bugs are difficult to reproduce because they depend on timing and state.
Memory pressure
Caching consumes memory. If cache grows unbounded or eviction strategy is poor, the application can run out of memory.
Cold start problems
When cache is empty (server restart, cache expiration), all requests hit the database simultaneously, causing load spikes.
Debugging difficulty
Caching adds a layer between application and data. Bugs may be caused by stale cache, invalidation failures, or race conditions that are difficult to reproduce.
When caching is premature
Avoid caching until performance problems are observed and measured.
Early in development
If the application is not slow, caching adds complexity without benefit. Build first, measure performance, then optimize.
Rapidly changing data
If data changes frequently, cache hit rates will be low and invalidation complexity high.
Low traffic
If the application serves few requests, database performance is usually sufficient. Caching optimizes for high concurrency.
Unique queries
If every query is different (personalized results, time-based filters), caching provides little value.
Where to cache
Application-level caching
In-memory caching (Redis, Memcached) sits between application and database. Good for shared data across multiple application instances.
Database query cache
Many databases cache query results automatically. Sufficient for many use cases without application changes.
HTTP caching (CDN, browser cache)
For public, rarely-changing content, HTTP caching offloads traffic entirely. Use Cache-Control headers.
Local in-process cache
Caching within the application process avoids network calls but does not share cache between instances.
Practical caching guidelines
- Measure first: identify slow operations with profiling before adding cache
- Start simple: use time-based expiration before complex invalidation
- Cache high up: cache complete responses rather than individual queries when possible
- Set eviction policies: use LRU (least recently used) to prevent unbounded growth
- Monitor cache effectiveness: track hit rates and memory usage
- Handle cache failures gracefully: application should work if cache is unavailable
- Document cache keys and TTLs: make invalidation logic explicit
Cache key design
Good cache keys prevent collisions and make invalidation easier.
Cache key patterns
user:{userId}
product:{productId}
search:{query}:{page}
report:{userId}:{date}
Cache key rules
- Include all parameters that affect the result
- Use consistent naming conventions
- Avoid including timestamps unless necessary
- Keep keys short to reduce memory overhead
Monitoring cache performance
Track cache effectiveness to know if it is helping.
Metrics to monitor
- Hit rate: percentage of requests served from cache
- Miss rate: percentage of requests requiring database lookup
- Eviction rate: how often entries are removed due to memory limits
- Memory usage: cache size and growth rate
- Latency reduction: difference between cached and uncached request times
Healthy cache metrics
- Hit rate above 70-80%
- Stable memory usage
- Low eviction rate
- Measurable latency improvement
Cache deliberately, not automatically
Caching is not a universal performance solution. It helps when data is read frequently, changes rarely, and staleness is acceptable. It creates problems when invalidation is complex, data changes often, or cache hit rates are low. Measure performance first, identify bottlenecks, then add caching where it provides clear value. Start simple with time-based expiration and only introduce complex invalidation strategies when necessary.
Published by the DSSS Engineering Team. For corrections or topic requests, use the contact page.